OmniVR-Flash
Single-step joint audio-video inference with a Turbo VAE encoder and decoder. Accepts a clip or a directory and exports restored picture and sound.
python infer.py --help
Flash setup and checkpoint requirements
Joint Audio-Video Conditional Generation
for Archival Footage Restoration
University of Science and Technology of China (USTC)
† Equal contribution ‡ Project leader ✉ Corresponding author
Manuscript updated 30 September 2026 · arXiv:2608.04224 · Flash & multistep inference code
Background: a historical clip restored by OmniVR
OmniVR restores archival picture and sound jointly, without user-provided text. The framework connects paired audiovisual data, condition annealing, OmniVR-Flash one-step inference, and evaluation of visual quality, audio quality, temporal consistency, and synchrony.
Archival footage often suffers from coupled visual and acoustic degradations, yet most restoration systems process the two modalities separately. To address this problem, we present OmniVR, the first systematic framework for joint audio-video restoration, covering data construction, model adaptation, efficient inference, and evaluation. We construct a high-quality audio-video corpus with detailed captions and use a joint degradation pipeline to produce aligned clean and degraded pairs. Using these pairs, we adapt a pretrained text-to-audio-video model (T2AV) by introducing degraded audio-video conditions (TAV2AV), then progressively replace sample captions with a fixed restoration prompt while retaining caption/null rehearsal. The resulting AV2AV model requires no user-provided text. Under a compatible residual-learning model, we prove that this condition-annealing schedule reduces gradient variance and expected restoration risk relative to direct fixed-prompt adaptation at the same training budget. For efficient deployment, OmniVR-Flash combines reduced-resolution video conditioning, MeanFlow-based one-step distillation, and Turbo VAE, achieving approximately 38 fps at 1K and 18 fps at 2K on a single B200 GPU. We further introduce OmniVRBench to evaluate four complementary dimensions: visual quality, audio quality, temporal consistency, and audio-visual synchrony. OmniVR achieves state-of-the-art results on public benchmarks and OmniVRBench. Data, code, and model weights will be released.
A systematic framework for joint audio-video restoration: data construction, staged adaptation, efficient inference, and four-axis evaluation.
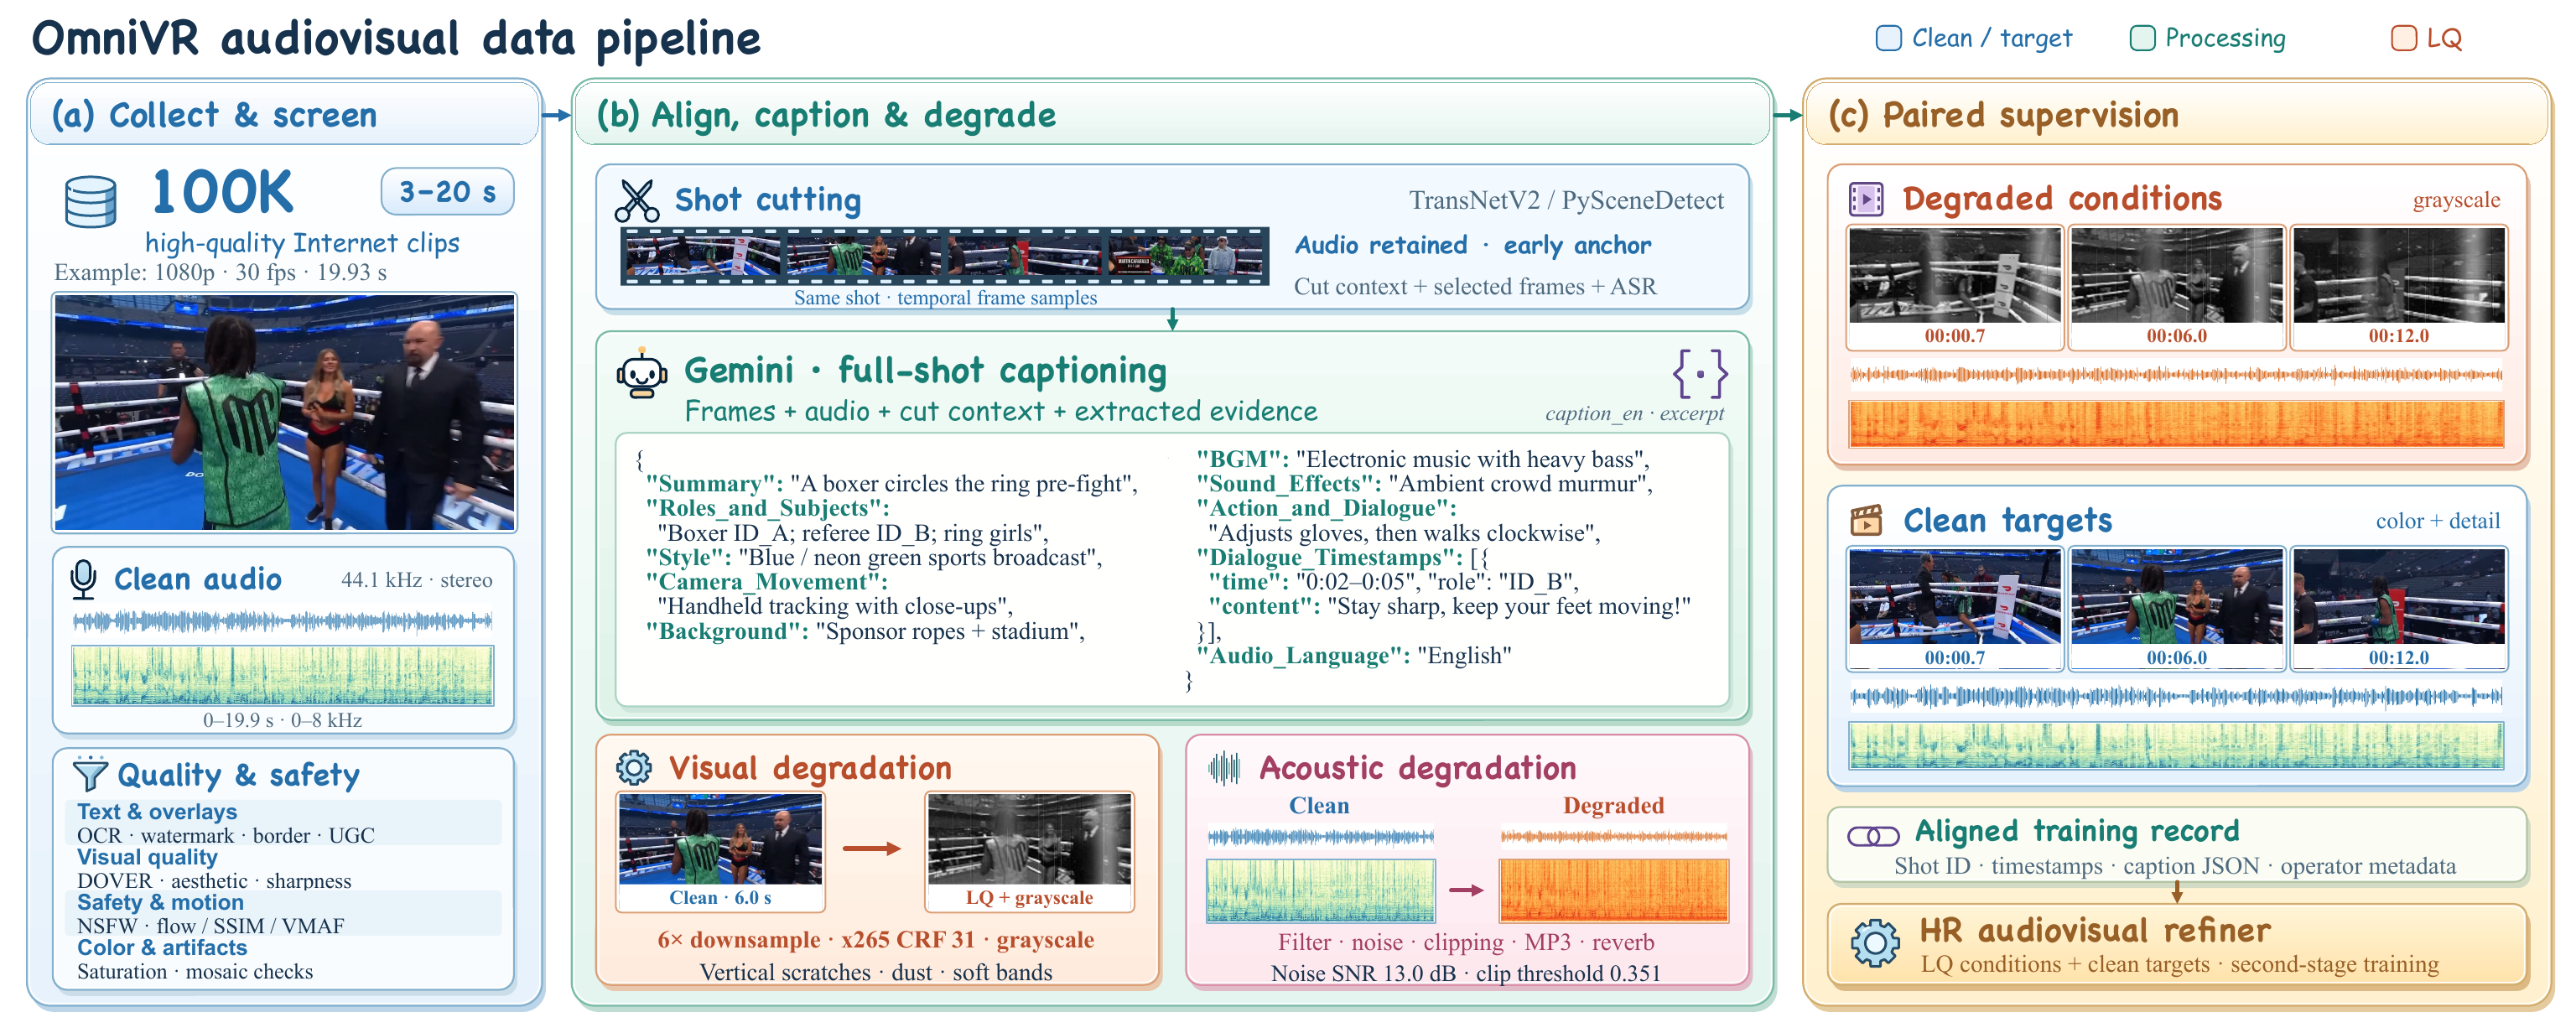
100K high-quality synchronized shots, detailed audiovisual captions, and a joint degradation pipeline provide aligned clean and degraded training pairs.
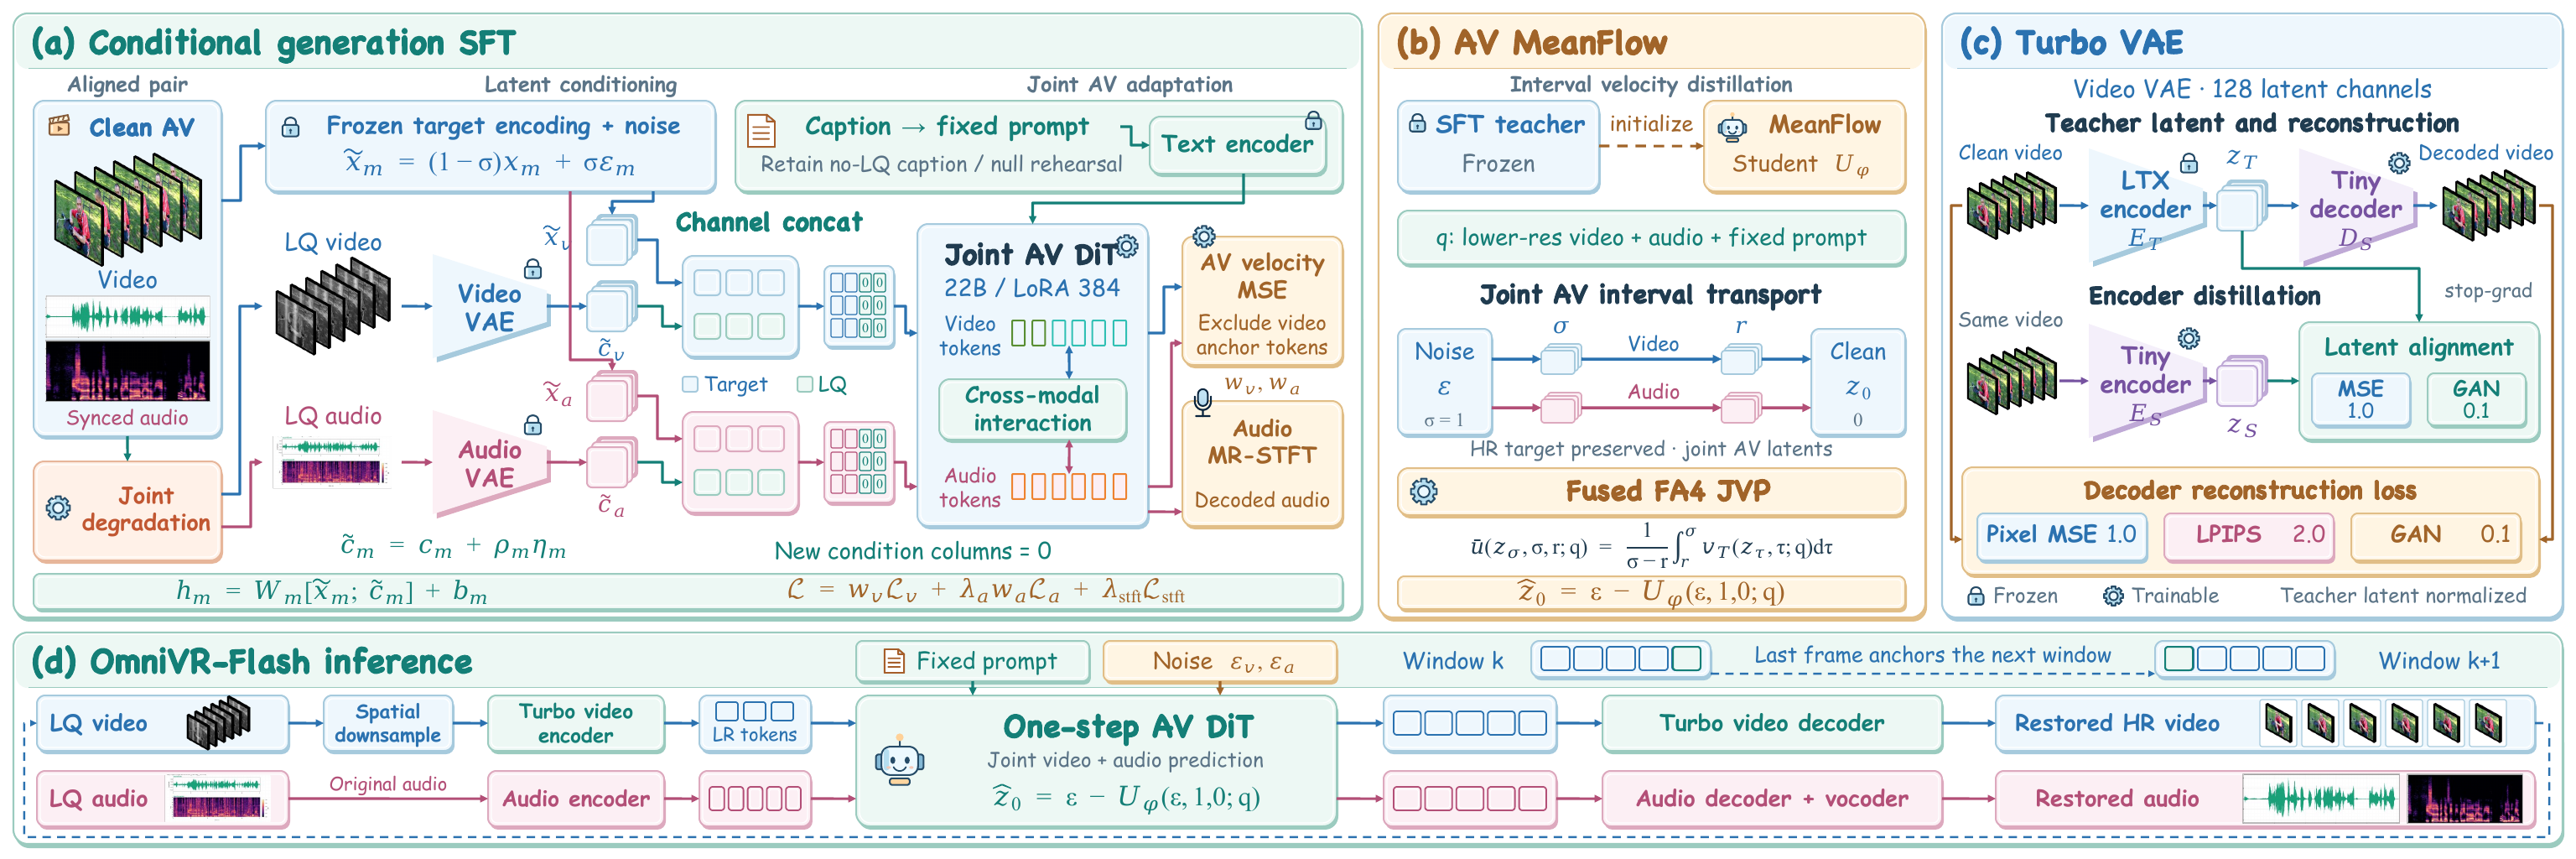
Gated condition annealing transfers control from sample captions to degraded audiovisual inputs while retaining caption/null rehearsal. Inference uses a fixed restoration prompt internally.
The paper combines reduced-resolution video conditioning, MeanFlow one-step distillation, and Turbo VAE, reporting approximately 38 fps at 1K and 18 fps at 2K on a single B200.
200 clips across controlled and real archival tracks evaluate visual quality, audio quality, temporal consistency, and audiovisual synchrony.
The source release includes both inference paths, their model loaders, and the shared LTX runtime. Install from one repository with Python 3.12 and a CUDA GPU.
Single-step joint audio-video inference with a Turbo VAE encoder and decoder. Accepts a clip or a directory and exports restored picture and sound.
python infer.py --help
Flash setup and checkpoint requirementsConfigurable Euler sampling with CFG/STG, full LTX VAE decoding, and per-video distribution across multiple GPUs. Public multistep checkpoints remain available.
python infer_multistep.py --help
Multistep setup and inferenceFlash code is included; compatible Flash LoRA, Turbo VAE, and prompt-cache artifacts are separate from the currently public multistep weights. The supplied commands process clip windows; see the release scope for the optimized paper configuration.
Drag the divider to wipe between the degraded input (left) and the OmniVR restoration (right). Then use the Hear the difference panel below to A/B the degraded vs restored soundtrack — hold either side to compare in place.
Press & hold either side to A/B in place · one track plays at a time
Frequency (low → high, bottom → top) over time · identical scale for both
Every pair is an independent slider. Drag any divider to compare input and restoration.
@article{lu2026omnivr,
  title={OmniVR: Joint Audio-Video Conditional Generation for Archival Footage Restoration},
  author={Lu, Xin and Fan, Zihao and Huang, Jie and Zhong, Mingchen and Zhang, Hexin and Fu, Xueyang and Zha, Zheng-Jun},
  journal={arXiv preprint arXiv:2608.04224},
  year={2026},
  eprint={2608.04224},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2608.04224}
}